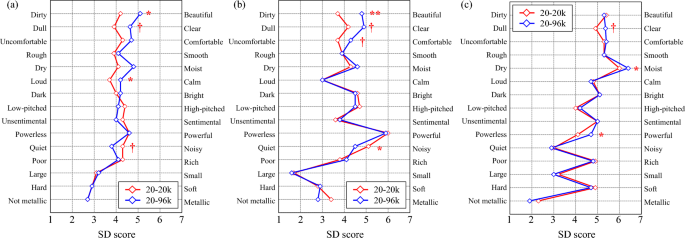

Also note that the downsampler used, Pyramix 6, is possibly not very good. If the version tested at https://src.infinitewave.ca/ is similar, I’m not surprised that differences might be audible. Sample rate has zero to do with it.I think we need to put that study into perspective:
Overall, the study is designed decently well, but there's a couple of additional caveats. First and foremost, there appear to be no checks of the actual performance of the ADC, software filter or playback system. So they didn't even check once how the frequency response looks. One funny example is that they report that their speakers can reproduce up to 33 kHz based on the spec sheet, but as far as I could find their amp rolls off past 22 kHz (again: based on specs)
- Each comparison (44.1 vs 88.2, 88.2 vs downsampled, 44.1 vs downsampled) was only repeated four times per listener
- The graph you show only reports the results for 13 of 16 listeners. They deliberately excluded three listeners' results because they deemed them significant of selecting the opposite of the correct choice. That is a weird way of excluding results which, in essence, simply didn't fit their narrative
- When accounting for all 16 listeners, only the Orchestra results for 44.1 vs 88.2 were significant
- Dividing relatively small sample sizes into more and more sub-groups runs into the multiple comparisons problem
- The XYZ vs downsampled comparisons essentially tell us only if the specific algorithm used in Pyramix 6 performs well
I would not exclude that effects like IMD or maybe a non-ideal filter in their software could have lead to audible effects. And there is a tiny trend emerging from the data which might indicate that. But to me, especially the weird decision to analyze three of the participants separately looks questionable and hints at the fact that they desperately wanted to report a positive finding.
EDIT: If you look at the combined data for all excerpts and add the 13 plus the 3 "outliers" together, the data scatters very, very close to 50% and is not significant for any of the three sample rate comparison pairs. You could argue that differences may be easier to hear on some types of music. But for music where nobody can hear a difference, the expected value is still 50% and yet, we deviate from that in both directions for the combined data set. From a purely statistical point you would expect that: Outliers to the positive and negative side of the 50% mark emerge by splitting the data into the different categories, resulting in a lower number of datapoints and higher uncertainty in each category.

If these studies fail to cover even the bare basics, what else did they fuck up?