• Welcome to ASR. There are many reviews of audio hardware and expert members to help answer your questions. Click here to have your audio equipment measured for free!

DAC listening test files - update

I tried again with the first two files, since I received my ZERO:2 IEM. These indeed are very good, and they let me hear more details, I thought, but that does not change anything:

Topping DX5 III – Low Gain (Vol -20dB), ZERO:2 IEM, driver exclusive mode, Filter = 3 (Sharp Linear).​


foo_abx 2.2.1 report
foobar2000 v2.1.5
2026-08-10 17:52:49

File A: file_1.wav
SHA1: 21b718084cbefae84cc1723ec49976b3c9ffa9ee
File B: file_2.wav
SHA1: 53949d842b273ee3b08edcc880344359b6e6ad50

Output:
Default : Speakers (2- TOPPING USB DAC) [exclusive], 32-bit
Crossfading: NO

17:52:49 : Test started.
17:56:44 : Test restarted.
17:56:44 : 01/01
17:57:14 : Test restarted.
17:57:14 : 02/02
17:58:03 : Test restarted.
17:58:03 : 03/03
17:58:22 : Test restarted.
17:58:22 : 04/04
17:58:37 : Test restarted.
17:58:37 : 04/05
17:58:52 : Test restarted.
17:58:52 : 05/06
17:59:08 : Test restarted.
17:59:08 : 06/07
17:59:21 : Test restarted.
17:59:21 : 07/08
17:59:48 : Test restarted.
17:59:48 : 08/09
18:00:15 : Test restarted.
18:00:15 : 09/10
18:00:32 : Test restarted.
18:00:32 : 09/11
18:01:14 : Test restarted.
18:01:14 : 10/12
18:01:45 : Test restarted.
18:01:45 : 10/13
18:01:58 : Test restarted.
18:01:58 : 10/14
18:02:42 : Test restarted.
18:02:42 : 10/15
18:03:13 : Test restarted.
18:03:13 : 11/16
18:03:13 : Test finished.

----------
Total: 11/16
p-value: 0.1051 (10.51%)

-- signature --
3876b32b4533d2b1cc8127e7007ac33f4dcfa6f6


>> FAIL

This concludes my tests for these two files.
 
I tested the two other files (DX5 vs D10s), and same fail:

foo_abx 2.2.1 report
foobar2000 v2.1.5
2026-08-10 18:29:04

File A: DAC1.wav
SHA1: 5326127cd74c39e30bfcb9af3a3d001fc99d4022
File B: DAC2.wav
SHA1: bd5db7393f6be9c4a0c4df088e1af149625ed47d

Output:
Default : Speakers (2- TOPPING USB DAC) [exclusive], 32-bit
Crossfading: NO

(...)
----------
Total: 11/16
p-value: 0.1051 (10.51%)

-- signature --
8cff98721131592b378712aba1e750ded64a15a3

I can't hear any difference. I'll need a dose of Delicate Sound Of Thunder now :p
 
Thank you for testing, Flo! It is tiring to test.
 
This is a bit of a tangent in this results-focused thread and I assume that you already have a similar view: The problem is simply that the differences those people report are biased results from rubbish testing. Casually listening to one DAC now any then another maybe an hour or even days apart, without level matching or any other proper control gives you absolutely no meaningful impression. All you end up with is some random ideas your brain created independent of any audible clues. So even if audible differences between excellent DACs did exist, they would not be remotely similar to what audiophiles report day in and day out.

As I've said before and as evident from many reports in this thread, proper blind testing is hard work. You need to be concentrated, you need a quiet environment and the right tools. It's neither casual nor easy and - if we're honest - not much fun after the first dozen or so repeats of some small 3 s excerpt played again and again ;)
Apologies if my post wasn’t clear. The point I was making is that I completely agree with the data based approach in this thread and what it tells us about audible differences in equipment.

Specifically I was saying that a skilled listener like @pedrojoaquimborges and others on this thread prove that any differences heard (if statistically valid) are so so minute that they are irrelevant to the subjective experience. Similar to changing a handful of random pixels on a 25 mega pixel image and suggesting it has any meaningful impact on the image when viewed at a comfortable viewing angle and size.
 
Right. And this thread is about finding differences between recorded files, by abx method, and not about sighted impressions. There are hundreds of threads dealing with sighted impressions. AlI - I had my long sighted period as well, of unreliable unsopported results. It ended when I was able to do properly prepared double blind tests. And do not think that if people have measuring abilities and education in electrical engineering and in acoustics means they are deaf and do not listen to music.
See my reply above to @RandomEar
 
One more test of two DACs, that I posted at ASR in January 2023.


It was Topping D10s vs. DacMagic+. Multi input preamp was used for the A/B test and the output of the preamp was recorded by Cosmos. In the link above there is a complete test schematics and description.
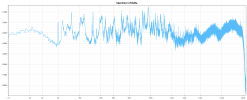
DeltaWave report is below. Anyone can tray the test and check the files.

2_DAC_delta.png

At the moment, we have one test of original file vs. DAC/ADC path and three DAC vs. DAC test recorded files. Anyone can check them and try ABX.
 

Attachments

I would like to add that I have just obtained a 10/16 result by random clicking on A and B buttons, without listening. So, in no way such a single result can be considered as indicating anything. It has similar low value as 8/10 result.
 

Attachments

I would like to add that I have just obtained a 10/16 result by random clicking on A and B buttons, without listening. So, in no way such a single result can be considered as indicating anything. It has similar low value as 8/10 result.
??? 10 out or 16 has probably of chance of 22% whereas 8 out of 10 is just 5.4%.
 
One more test of two DACs, that I posted at ASR in January 2023.


It was Topping D10s vs. DacMagic+. Multi input preamp was used for the A/B test and the output of the preamp was recorded by Cosmos. In the link above there is a complete test schematics and description.
DeltaWave report is below. Anyone can tray the test and check the files.

View attachment 550904

At the moment, we have one test of original file vs. DAC/ADC path and three DAC vs. DAC test recorded files. Anyone can check them and try ABX.
Came back to work today, so I'm finally testing from a better setup (Neumann KH310 through Focusrite Clarett+ converters).

Tried to ABX test these two files (DacMagic+ vs D10) and called it a day after two rounds - wasn't able to tell them apart in the slightest, and not for lack of trying. I believe there's absolutely no point clicking through a test randomly just to provide insignificant/arbitrary results. I'm also very impressed/shocked at how low the amplitude of the delta signal is on a null test.

EDIT:

Ran another round of the very first rest (original recording vs E1DA Cosmos) and very strenuously got another 12/16 (dactest_abx7 attached below).

Also ran a test for the Topping DX5 vs D10 comparison and managed to delude myself into finding a difference in a single hi hat hit towards the end of the track. Was swiftly brought back to reality by a 7/16 result (dactest2_ abx2 attached below). I conclude that I'm very very happy with the converter tech we have available at the moment.

I believe the next step in research is twofold: a) understanding how many high quality conversion steps (in series) degrade the signal in a perceptible way; b) finding the perceptible lower end threshold for converter quality and equating it to objective measurements.
 

Attachments

Last edited:
@amirm : This 8/10 foobar ABX result I have obtained when I have repeated the abx tests each with 10 trials 5x. I needed only few minutes to get it. I am saying that 8/10 positive result is statistically insufficient and should be repeated 3x to make a point. 1x is pointless. Thus I insist on at least 16 trials and better repeat such success.
 

Attachments

One more test of two DACs, that I posted at ASR in January 2023.


It was Topping D10s vs. DacMagic+. Multi input preamp was used for the A/B test and the output of the preamp was recorded by Cosmos. In the link above there is a complete test schematics and description.
DeltaWave report is below. Anyone can tray the test and check the files.

View attachment 550904

At the moment, we have one test of original file vs. DAC/ADC path and three DAC vs. DAC test recorded files. Anyone can check them and try ABX.
As with the other comparison between DACs, the delta ff the spectrum has passband ripple on the order of 0.05dB. When you remove this with Level EQ the PK metric is better than -110dB.

I am very interested in what improvement you get in recordings vs original track now that you have removed AC coupling from recordings. But also, it should be noted that anyone with the E1DA Cosmos should be able to record DACs and compare them against each other. I might do that with a decent DAC vs something cheap like the DAC in my TV.
 
I did not even dare to compete in ABX; my brain stops all analysis when confronted with this music choice; swapped some twenty times between the files for seconds, but no difference audible for me.
Maybe tomorrow after a long sleep it will be better.
BTW: 2/16 is far beyond statistical noise: are you not concerned you simply did A for B ?
Foobar ABX is a one-sided test. We can indeed exclude this hypothesis by going two-sided test and p-value results.

That way you are no longer just testing "Can I hear a difference?" but "Am I systematically fooling myself?".

With that exemple of 2 correct out of 16 trials, the difference is:
  • One-sided view: Foobar looks at this and gives you a terrible p-value (around 0.99). It assumes you just failed completely.
  • Two-sided view: A two-sided calculation recognizes that getting only 2 right is statistically just as rare and unnatural as getting 14 right. You’re getting a p-value of 0.0042 and that is statistically relevant.
So we can use Foobar exactly the same way but request two-sided p-value results. This means we need to double the p-value that Foobar shows (provided the result is <0.5).

The inconvenience is that two-sided are more difficult to satisfy if we keep the <0.05 standard threshold. But when we know/assume the differences between two DACs are so tiny, I think it is not a bad idea to go that way.

I might elaborate on that.

I’m really rusty on statistics, it’s from 30 years ago and I’ve never used what I learnt at the university. If I got it all wrong, feel free to slap me.
 
  • Two-sided view: A two-sided calculation recognizes that getting only 2 right is statistically just as rare and unnatural as getting 14 right. You’re getting a p-value of 0.0042 and that is statistically relevant.
It is true about statistically just as rare. I can see getting it backwards in one ABX round where you just remembered the A and B backwards and were making choices just by listening to X. But if you see the results, wouldn't you try to get that fixed for the next round? If you try to fix what you are doing in an effort to get a positive result and the result keeps being something like 2 out of 16, wouldn't you think you are just very unlucky rather than believing you are a talented backwards identifier? Clearly I have layperson's understanding here; maybe there is a better way to look at it.
 
That’s the beauty of going two-sided, no need to think more than getting the results and processing them that way. In reality, it makes passing harder. Let me try to make it more tangible (I’m already on it), because it is not the only factor in that type of test (thinking the previous discussion about the significance of 8/10 score).
 
Interesting thread.

Question: Could tests like these be created to identify what threshold of volume difference people can reliably detect? Maybe that’s already been done?
 
The less number of trials, the more we desire to be well below the 0.05 threshold.

Like I said above, the important info is that Foobar ABX is a one-sided test. It means that we mathematically assume that it is impossible for a listener to consistently misidentify the DACs (or prefer the opposite). I think the reality tells us a two-sided test is more conservative, especially considering we assume the differences to be tiny between two DACs.

On a mathematical perspective, two-sided multiplies by two the p-value (again provided a one-sided result below 0.5). It means the test is more conservative. It requires stronger evidence to prove a statistical difference, which protects us from methodology error.

Talking about a trial of 8/10 (Amir’s point of suggestive result): it means a one-sided p-value of 0.547, which above the 0.05 threshold, and if it seems suggestive, it is not statistically significant. Two-sided p makes it 0.109, clearly above the 0.05 mark. For a test where we assume tiny differences, it is reasonable to go two-sided p-value calculation, especially with a low number of trials.
With a score of 9/10, one-sided p is 0.01 and two-sided p is 0.02, both well below the 0.05 threshold, and that is a massive difference.

EDIT: all the below is wrong, I leave it so the thread is understood.
By the way, talking about total number, and again because of the assumed tiny differences, we should go 100 to 300 tests. It means that 6 people running the Foobar ABX (providing their p-value for 16 trials each) with a two-sided p calculation should put us in a comfortable zone to be conclusive.

Key Takeaways:

  • If we assume the differences are tiny between DACs, then we want more trials, not less.
  • 7 people running one ABX Foobar (16) test provides us with a total of 7x16=112 tests.
  • Two-sided p-value calculation renders the end-results unquestionable.

Real Life Example

With the tests proposed by pma, if I combine all results from all members who participated in one or both tests (@RandomEar : 6/16, 7/16, @pjug :10/16, @Holy Spirit: 8/16, @pma : 8/16, 10/16 (random clicking), @Sokel : 2/16, 3/16, @staticV3 : 8/20, @NTTY : 10/16, 5/16, 6/16, 8/16, 13/16, 9/16, 11/16), I get the below:

  • 7 participants
  • 260 tests
  • 124 positives
  • 124/260 means 0.2476 one-sided p and 0.4952 two-sided p.
Funny thing is that if I add the 8/10 result of Josh to that, then 132/270 means 0.38 one-sided p and 0.76 two-sided p. What seemed suggestive (8/10) now makes the result fully consistent with random guessing.

Conclusion

The above results are not statistically significant. A score of 124/260 is very close to the 50% expected from random guessing, so there is no evidence of discrimination ability (nor of systematically choosing the wrong answer).

Adding the score of Josh makes the result fully consistent with random guessing.
 
Last edited:
The less number of trials, the more we desire to be well below the 0.05 threshold.

Like I said above, the important info is that Foobar ABX is a one-sided test. It means that we mathematically assume that it is impossible for a listener to consistently misidentify the DACs (or prefer the opposite). I think the reality tells us a two-sided test is more conservative, especially considering we assume the differences to be tiny between two DACs.

On a mathematical perspective, two-sided multiplies by two the p-value (again provided a one-sided result below 0.5). It means the test is more conservative. It requires stronger evidence to prove a statistical difference, which protects us from methodology error.

Talking about a trial of 8/10: it means a one-sided p-value of 0.547, which above the 0.05 threshold, and if it seems suggestive, it is not statistically significant. Two-sided p makes it 0.109, clearly above the 0.05 mark. For a test where we assume tiny differences, it is reasonable to go two-sided p-value calculation, especially with a low number of trials.
With a score of 9/10, one-sided p is 0.01 and two-sided p is 0.02, both well below the 0.05 threshold, and that is a massive difference.

By the way, talking about total number, and again because of the assumed tiny differences, we should go 100 to 300 tests. It means that 6 people running the Foobar ABX (providing their p-value for 16 trials each) with a two-sided p calculation should put us in a comfortable zone to be conclusive.

Key Takeaways:
  • If we assume the differences are tiny between DACs, then we want more trials, not less.
  • 7 people running one ABX Foobar (16) test provides us with a total of 7x16=112 tests.
  • Two-sided p-value calculation renders the end-results unquestionable.

Real Life Example

With the tests proposed by pma, if I combine all results from all members who participated in one or both tests (@RandomEar : 6/16, 7/16, @pjug :10/16, @Holy Spirit: 8/16, @pma : 8/16, 10/16 (random clicking), @Sokel : 2/16, 3/16, @staticV3 : 8/20, @NTTY : 10/16, 5/16, 6/16, 8/16, 13/16, 9/16, 11/16), I get the below:
  • 7 participants
  • 260 tests
  • 124 positives
  • 124/260 means 0.2476 one-sided p and 0.4952 two-sided p.
Funny thing is that if I add the 8/10 result of Josh to that, then 132/270 means 0.38 one-sided p and 0.76 two-sided p. What seemed suggestive (8/10) now makes the result fully consistent with random guessing.

Conclusion

The above results are not statistically significant. A score of 124/260 is very close to the 50% expected from random guessing, so there is no evidence of discrimination ability (nor of systematically choosing the wrong answer).

Adding the score of Josh makes the result fully consistent with random guessing.
Is Foobar a one sided test or just one sided scoring statistics?
 
Interesting thread.

Question: Could tests like these be created to identify what threshold of volume difference people can reliably detect? Maybe that’s already been done?
Some info is collected here and I did add some testing of my own a couple of posts further down. But I didn't upload the files, yet - mostly due to their size. And it's not a standalone thread on that specific topic.
 
Interesting thread.

Question: Could tests like these be created to identify what threshold of volume difference people can reliably detect? Maybe that’s already been done?
Yes, there are numerous scientific (not pseudoscientific) publications on this theme. You will definitely find great number of them when you make your web search, AI will help you. I am sorry but I am lazy and do not have enough energy to do it, I am completely concentrated on a real job.
 
Back
Top Bottom