Hello! With the admins’ permission, I’d like to introduce an open-source project I’m currently developing, ask for feedback, and invite anyone interested to contribute.
When I was younger, I enjoyed listening to music, watching movies, and modifying speakers.
That was how I learned about using crossovers to divide frequency ranges between different speaker drivers.
Later, I began wondering: what if, instead of separating audio by “frequency,” we used AI to separate it by “sound source”—such as vocals, drums, bass, and other instruments—and then routed each stem to a separate speaker or output channel?
What would the result sound like?
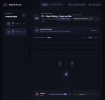
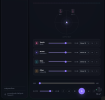
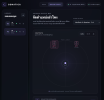
I couldn’t find any consumer-friendly software that supported this kind of workflow, so I started an open-source project called Sonatica, with Codex helping me develop it.
Without tools like this, I probably wouldn’t have been able to build it on my own.
The audio source-separation model itself does not use an LLM. LLMs and Codex are simply tools I use to help design and develop the application.
GitHub: https://github.com/777CC/Sonatica
> Patent question
During my preliminary research, I found three potentially relevant patent documents:
https://patents.google.com/patent/US12395805B2/en
https://patents.google.com/patent/EP4131250B1/fr
https://patents.google.com/patent/US20170301330A1/en
I understand that responses in this group do not constitute legal advice, but I would appreciate some initial guidance on what I should research and how I might proceed.
> Audio quality
I’m not ready to claim that the sound is objectively “better,” since source separation can introduce artifacts. However, in my experiments, routing each stem to a separate speaker made the vocals and individual instruments sound more distinct and detailed.
If you have a multi-output audio interface—or would like to help test the application on Windows, macOS, or Linux—I’d be very grateful. Contributions involving audio DSP, Python, Rust/Tauri, or UI/UX are also very welcome.
If you find the project useful and would like to help cover token costs or contribute toward audio interfaces and speakers for testing, please feel free to contact me.
All support is entirely optional. The software will remain open source and free to use.
When I was younger, I enjoyed listening to music, watching movies, and modifying speakers.
That was how I learned about using crossovers to divide frequency ranges between different speaker drivers.
Later, I began wondering: what if, instead of separating audio by “frequency,” we used AI to separate it by “sound source”—such as vocals, drums, bass, and other instruments—and then routed each stem to a separate speaker or output channel?
What would the result sound like?
I couldn’t find any consumer-friendly software that supported this kind of workflow, so I started an open-source project called Sonatica, with Codex helping me develop it.
Without tools like this, I probably wouldn’t have been able to build it on my own.
The audio source-separation model itself does not use an LLM. LLMs and Codex are simply tools I use to help design and develop the application.
GitHub: https://github.com/777CC/Sonatica
> Patent question
During my preliminary research, I found three potentially relevant patent documents:
https://patents.google.com/patent/US12395805B2/en
https://patents.google.com/patent/EP4131250B1/fr
https://patents.google.com/patent/US20170301330A1/en
I understand that responses in this group do not constitute legal advice, but I would appreciate some initial guidance on what I should research and how I might proceed.
> Audio quality
I’m not ready to claim that the sound is objectively “better,” since source separation can introduce artifacts. However, in my experiments, routing each stem to a separate speaker made the vocals and individual instruments sound more distinct and detailed.
If you have a multi-output audio interface—or would like to help test the application on Windows, macOS, or Linux—I’d be very grateful. Contributions involving audio DSP, Python, Rust/Tauri, or UI/UX are also very welcome.
If you find the project useful and would like to help cover token costs or contribute toward audio interfaces and speakers for testing, please feel free to contact me.
All support is entirely optional. The software will remain open source and free to use.
Attachments
Last edited:


